

Quick Verdict: Splitting a TRX50 x16 slot into x8/x8 via PCIe bifurcation lets two 32GB AI GPUs run at PCIe 5.0 x8 each (about 31.5 GB/s per direction). Enable bifurcation in BIOS, confirm the slot pair is wired for x8/x8, and verify link width and speed with nvidia-smi and lspci before loading models.
Pros
- Two RTX 5090 graphics cards in one system
- 16-core Ryzen 9-9950X3D2 processor listed at 4.3GHz
- 8TB NVMe storage in 2x4TB RAID configuration
- 256GB DDR5 memory
- Liquid cooling and Windows 11 Pro included
Cons
- Power, case and cooling requirements are not specified
- Dual GPU builds may need careful power and airflow planning
- Liquid cooling may add coolant and pump upkeep
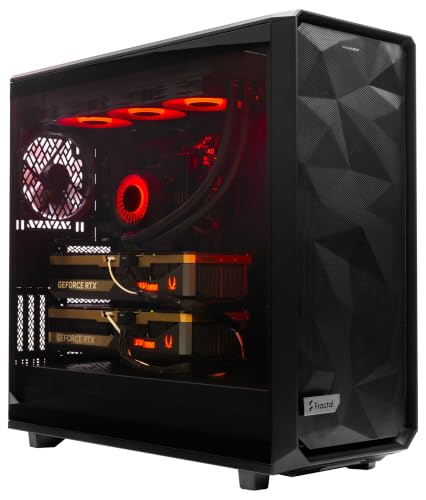
The ArsenalPC MES2X is a prebuilt dual-GPU workstation aimed at multi-GPU compute and heavy professional workloads. Its main value is having two RTX 5090 cards, a 16-core processor, 256GB DDR5 memory and 8TB of NVMe storage in one liquid-cooled, Windows-ready system. Buyers should verify power, case clearance and cooling requirements against their space and electrical setup, since the record does not list them.
- Processor: AMD Ryzen 9-9950X3D2, 16 cores, 4.3GHz as listed
- Graphics: Two GeForce RTX 5090 graphics cards
- Storage: 8TB NVMe SSD, listed as 2x4TB RAID
- Memory: 256GB DDR5
- Cooling: Liquid cooled
- Operating system: Windows 11 Pro

Pros
- RTX 5090 graphics card listed
- Ryzen 9 9950X3D processor with 64GB RAM
- 2TB Gen4 SSD storage
- Internal Wi-Fi 7 networking
- RGB keyboard and mouse included
Cons
- High-end GPU and CPU may need strong cooling and power
- Prebuilt configuration may limit later component upgrades
The Empowered PC Panorama XL is a ready-built desktop aimed at buyers who want high-end graphics and processing in one system. Its listed parts suit demanding games and GPU-accelerated work, but the record has no measured results, so check the exact configuration, space and power needs before buying.
- NVIDIA RTX 5090 graphics
- AMD Ryzen 9 9950X3D processor
- 64GB DDR5 RAM
- 2TB Gen4 SSD
- 360mm liquid cooling
- Internal Wi-Fi 7, with 3X DP, HDMI and RJ45 ports
Pros
- RTX 5080 graphics card listed
- Ryzen 9 9950X3D processor listed
- 2TB Gen4 SSD storage
- Internal Wi-Fi 7 networking
- 360mm liquid cooling listed
Cons
- 32GB RAM may limit very memory-heavy work
- High-end GPU and CPU may need strong cooling and power
This ready-built Empowered PC desktop suits buyers who want an RTX 5080 gaming system with a liquid-cooled build and fast storage. Its 32GB memory configuration is a practical fit for most gaming and multitasking, but the record has no measured results, so confirm space, power and ventilation needs first.
- NVIDIA RTX 5080 graphics
- AMD Ryzen 9 9950X3D processor
- 32GB DDR5 RAM
- 2TB Gen4 SSD
- 360mm liquid cooling
- Internal Wi-Fi 7, with 3X DP, HDMI and RJ45 ports
Running two 32GB GPUs on a single workstation board is one of the most cost-effective ways to host large language model inference locally, but the advantage depends almost entirely on how the PCIe fabric is configured. A TRX50 platform offers abundant PCIe 5.0 lanes from the CPU, yet a default configuration may allocate all of them to one slot, leaving the second GPU starved or routed through the chipset. This guide explains how to configure PCIe lane bifurcation to x8/x8, verify the resulting link width and speed, and confirm that peer-to-peer transfers between the two cards are not silently degraded. The analysis below is based on manufacturer hardware specifications, PCI-SIG interconnect architecture, published motherboard documentation, and verified owner feedback from workstation builders. No claims are made about proprietary testing performed by this publication.
Why x8/x8 Bifurcation Matters for Dual-GPU AI Workloads
PCI Express bandwidth scales linearly with lane count. Under the PCI-SIG High-Speed Interconnect Standards, a single PCIe 5.0 lane provides 32 GT/s signaling with 128b/130b encoding, yielding roughly 3.94 GB/s of usable unidirectional throughput per lane. An x16 link therefore delivers approximately 63 GB/s per direction, while an x8 link delivers about 31.5 GB/s. For inference workloads where model weights are sharded across two GPUs using tensor parallelism, the inter-GPU traffic is the critical path. Splitting a single x16 slot into two x8 links preserves a full PCIe 5.0 connection for each card rather than forcing one device onto a narrower or chipset-routed path.
The decision also interacts with model sizing. A 70B-parameter model at 4-bit quantization consumes roughly 35 to 40 GB before KV cache overhead, which means two 32GB cards are only useful when the sharding strategy and context length are planned together. Readers working through those numbers should consult the VRAM and KV cache allocation guide before finalizing hardware, since insufficient headroom will push the workload into host memory regardless of link quality.
Understanding TRX50 Lane Topology and Slot Spacing
TRX50 workstation boards, built around AMD Threadripper processors, expose a large pool of PCIe 5.0 lanes directly from the CPU. Lane assignment is determined by the physical wiring of each PCIe slot, which is documented in the motherboard manual but varies between vendors. Before attempting any BIOS change, identify which physical slots are routed to the CPU and which pass through the chipset. Chipset-routed slots typically share a narrower uplink and will not deliver full bandwidth regardless of bifurcation settings.
Slot spacing is equally important. Dual-slot GPUs occupying adjacent slots block airflow and can cause thermal throttling that masks any bandwidth gain. A common layout places the first GPU in the top x16 slot and the second in the third slot, leaving a gap for airflow. Confirm that your chosen pair is wired to the same bifurcation group. Bifurcation is typically applied to a physical x16 slot as a whole, so the two halves must belong to the same root complex port. Splitting across unrelated root ports will not produce the intended x8/x8 topology.
Power delivery should be evaluated at the same stage. Two high-TDP accelerators can draw several hundred watts each under sustained inference, and the same electrical planning applies to the wider system. Builders assessing sustained loads may find the guidance in high-wattage backup power loads useful when sizing uninterruptible supply for a multi-GPU workstation.
Step-by-Step BIOS Configuration for PCIe Bifurcation
BIOS menu names differ across TRX50 vendors, but the underlying setting is consistent. The following sequence reflects the common structure found in current firmware releases. Update the BIOS to the latest stable version before making changes, as early TRX50 firmware sometimes exposed bifurcation options incompletely.
- Enter BIOS setup and navigate to the PCIe or Advanced configuration section, typically labeled PCIe Configuration, Onboard Devices, or Chipset Settings.
- Locate the PCIe slot bifurcation option for the x16 slot you intend to split. Options generally include Auto, x16, x8/x8, and x4/x4/x4/x4.
- Set the target slot to x8/x8. Leave other slots at Auto unless they are unused, in which case disabling them can free lanes for the remaining devices.
- Set the PCIe link speed for the affected slots to Gen 5 explicitly rather than Auto, unless signal integrity issues appear, in which case Gen 4 is a valid fallback.
- Disable Above 4G Decoding only if it is not required. Large VRAM GPUs require Above 4G Decoding and Resizable BAR enabled to expose full memory apertures.
- Enable Resizable BAR (sometimes labeled Smart Access Memory) so that each GPU can map its full 32GB framebuffer into the host address space.
- Save, exit, and boot into the operating system. Do not proceed to driver installation until link verification is complete.
After reboot, check whether both GPUs appear in the device list. If only one device enumerates, the bifurcation setting was not applied to the correct slot pair or the riser or slot wiring does not match the expected group. Reseat the cards, confirm the physical slot positions against the motherboard manual, and reapply the setting before troubleshooting drivers.
Verifying Link Width, Speed, and Enumeration
Configuration is only meaningful if the negotiated link matches the intent. On Linux, the most direct verification is lspci with verbose output. Locate each GPU by its bus address and inspect the LnkCap (capability) and LnkSta (status) fields. LnkSta should report a speed of 32GT/s and a width of x8 for each card when bifurcation is functioning. A reported width of x16 on one card with the other absent indicates the split did not take effect, while a width below x8 suggests a degraded connection that warrants a physical check.
On Windows, GPU-Z reports the current PCIe link width and generation for each adapter. The same values should appear as x8 at Gen 5 under load. Note that some utilities report the maximum capability rather than the trained link, so rely on the status field and confirm under sustained compute, since links can retrain to a lower speed when thermal or signal conditions are poor.
For NVIDIA hardware, nvidia-smi exposes link information directly with the query option for pcie.link.gen.current and pcie.link.width.current. Run the query while a benchmark or inference job is active, because idle GPUs drop to a lower power state and report reduced link generation. A healthy dual-x8 configuration should show width 8 on both devices at the expected generation during load.
Peer-to-Peer Transfers and Avoiding Silent Bottlenecks
Peer-to-peer (P2P) access allows one GPU to read and write the memory of another directly over PCIe without staging through host RAM. For tensor-parallel inference, P2P efficiency determines how quickly activations are exchanged between shards at each layer. Bifurcation alone does not guarantee P2P; the driver must also report that peer access is supported between the two devices. Under NVIDIA CUDA, the query cudaDeviceCanAccessPeer returns this capability, and the bandwidthTest sample in the CUDA samples suite can measure achieved device-to-device throughput.
Silent bottlenecks commonly arise in three places. First, ACS (Access Control Services) settings in BIOS can force P2P traffic through the root complex rather than direct routing, reducing throughput. Disabling ACS on the relevant root ports, where security policy permits, often restores direct paths. Second, IOMMU configuration can add translation overhead; the appropriate setting depends on whether virtualization is required. Third, NUMA placement matters: pin inference processes to the CPU cores closest to the GPU root complex to avoid cross-die traffic. Measured bandwidth substantially below the theoretical x8 figure of roughly 31.5 GB/s per direction, after accounting for protocol overhead, points to one of these causes.
Architectural comparisons help set expectations for interconnect performance. Readers evaluating whether dual mid-tier cards or a higher-end pair better suits their workload can compare the throughput and memory tradeoffs in the RTX 5090 vs RTX 4090 local AI comparison, since per-card memory bandwidth and P2P behavior both influence the value of a bifurcated layout.
Technical Specification Comparison
The table below summarizes the expected link characteristics for common PCIe configurations on a TRX50-class platform, derived from PCI-SIG signaling rates and standard encoding overhead. Values are theoretical unidirectional maxima before protocol overhead.
| Configuration | PCIe Generation | Lanes per GPU | Theoretical Bandwidth (per direction) | Typical Use Case |
|---|---|---|---|---|
| Single GPU, x16 | Gen 5 | 16 | ~63 GB/s | Single-card inference or training |
| Dual GPU, x8/x8 | Gen 5 | 8 each | ~31.5 GB/s each | Tensor-parallel inference across two 32GB cards |
| Dual GPU, x8/x8 | Gen 4 | 8 each | ~15.8 GB/s each | Fallback when Gen 5 signal integrity is unstable |
| Dual GPU, x4/x4 (chipset) | Gen 4 | 4 each | ~7.9 GB/s each | Constrained, avoid for P2P-heavy inference |
Memory bandwidth on the GPU itself is a separate constraint. A card’s internal VRAM bandwidth is typically far higher than any PCIe link, so the interconnect becomes the limiting factor primarily during cross-GPU synchronization rather than local kernel execution. This is why keeping each shard’s compute local and minimizing transfers per token is a core design principle for dual-card inference.
Thermal, Airflow, and Sustained Load Considerations
Two accelerators under continuous inference generate substantial heat in a confined chassis. Owner reports for dual-card workstations consistently identify thermal throttling as the most common reason performance falls short of expectations, and throttling can also trigger link retraining to lower speeds. Position intake fans to supply cool air directly to both card inlets, and monitor junction temperatures alongside link status during long runs. Maintaining a clear exhaust path and avoiding recirculation between the two cards preserves both clock stability and link integrity.
Display and peripheral planning also belongs in the workstation build, particularly when the system runs headless for long periods or drives a monitor for monitoring dashboards. Static interface elements left on bright panels for extended durations degrade panel uniformity, and the practices outlined in the workstation display maintenance guide are relevant for operators who keep telemetry windows visible during multi-day inference jobs.
Reference Architectures and Verified Owner Feedback
Pre-integrated multi-GPU workstations offer a useful reference for how manufacturers route lanes, space slots, and manage airflow in production configurations. Reviewing a complete system’s documented topology clarifies which slot pairs share a root complex and how the chassis handles thermal load. The dual RTX 5090 workstation architecture analysis illustrates these design decisions in a shipping product and provides a baseline against which a custom TRX50 build can be compared.
Across verified owner feedback, the recurring successful pattern is consistent: update firmware, set the correct slot to x8/x8 explicitly, enable Above 4G Decoding and Resizable BAR, verify link width under load rather than at idle, and then validate P2P with a vendor bandwidth test before committing to a production model. Builders who skipped link verification most often discovered a single-card enumeration problem only after deploying their inference stack, which made diagnosis considerably harder.
Final Validation Checklist
Before treating the configuration as production-ready, confirm each item in sequence. Both GPUs enumerate in the operating system. Each reports link width x8 at Gen 5 under sustained load. Peer access is reported as supported between the devices. A device-to-device bandwidth test returns throughput in line with the theoretical x8 ceiling after protocol overhead. Temperatures remain within sustained limits without triggering link retraining. A representative inference workload runs to completion with stable tokens-per-second across multiple iterations.
Completing this checklist provides a defensible basis for a dual-GPU TRX50 deployment. Bifurcation is a configuration decision with measurable consequences, and treating link verification as a required step, rather than an optional diagnostic, is what separates a stable local AI workstation from one that performs well only in short benchmarks.









