

Quick Verdict: Splitting a large LLM across two GPUs and system DDR5 is viable when you map layers deliberately: keep attention and early layers resident in VRAM, assign contiguous layer blocks per GPU to minimize cross-device traffic, and offload only the remainder to host memory. llama.cpp handles this through layer-split and tensor-split controls, while vLLM relies on tensor parallelism over NVLink or PCIe. Offloading to DDR5 trades token throughput for capacity, so the ratio must be tuned to avoid PCIe saturation.
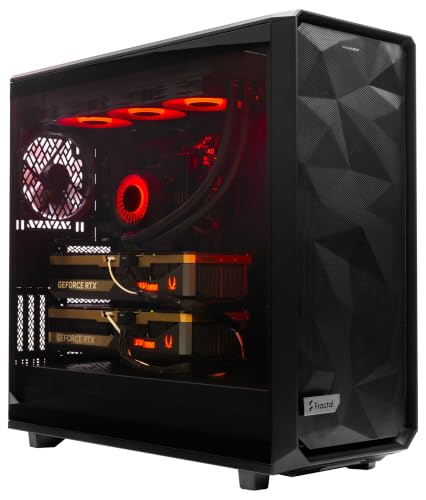
Pros
- Two RTX 5090 graphics cards in one system
- 16-core Ryzen 9-9950X3D2 processor listed at 4.3GHz
- 8TB NVMe storage in 2x4TB RAID configuration
- 256GB DDR5 memory
- Liquid cooling and Windows 11 Pro included
Cons
- Power, case and cooling requirements are not specified
- Dual GPU builds may need careful power and airflow planning
- Liquid cooling may add coolant and pump upkeep
The ArsenalPC MES2X is a prebuilt dual-GPU workstation aimed at multi-GPU compute and heavy professional workloads. Its main value is having two RTX 5090 cards, a 16-core processor, 256GB DDR5 memory and 8TB of NVMe storage in one liquid-cooled, Windows-ready system. Buyers should verify power, case clearance and cooling requirements against their space and electrical setup, since the record does not list them.
- Processor: AMD Ryzen 9-9950X3D2, 16 cores, 4.3GHz as listed
- Graphics: Two GeForce RTX 5090 graphics cards
- Storage: 8TB NVMe SSD, listed as 2x4TB RAID
- Memory: 256GB DDR5
- Cooling: Liquid cooled
- Operating system: Windows 11 Pro

Pros
- RTX 5090 graphics card listed
- Ryzen 9 9950X3D processor with 64GB RAM
- 2TB Gen4 SSD storage
- Internal Wi-Fi 7 networking
- RGB keyboard and mouse included
Cons
- High-end GPU and CPU may need strong cooling and power
- Prebuilt configuration may limit later component upgrades
The Empowered PC Panorama XL is a ready-built desktop aimed at buyers who want high-end graphics and processing in one system. Its listed parts suit demanding games and GPU-accelerated work, but the record has no measured results, so check the exact configuration, space and power needs before buying.
- NVIDIA RTX 5090 graphics
- AMD Ryzen 9 9950X3D processor
- 64GB DDR5 RAM
- 2TB Gen4 SSD
- 360mm liquid cooling
- Internal Wi-Fi 7, with 3X DP, HDMI and RJ45 ports
Pros
- RTX 5080 graphics card listed
- Ryzen 9 9950X3D processor listed
- 2TB Gen4 SSD storage
- Internal Wi-Fi 7 networking
- 360mm liquid cooling listed
Cons
- 32GB RAM may limit very memory-heavy work
- High-end GPU and CPU may need strong cooling and power
This ready-built Empowered PC desktop suits buyers who want an RTX 5080 gaming system with a liquid-cooled build and fast storage. Its 32GB memory configuration is a practical fit for most gaming and multitasking, but the record has no measured results, so confirm space, power and ventilation needs first.
- NVIDIA RTX 5080 graphics
- AMD Ryzen 9 9950X3D processor
- 32GB DDR5 RAM
- 2TB Gen4 SSD
- 360mm liquid cooling
- Internal Wi-Fi 7, with 3X DP, HDMI and RJ45 ports
Running a 70B-class or larger model locally rarely fits inside a single consumer GPU. The practical solution is to distribute model weights across two accelerators and, when necessary, spill the remaining layers into system DDR5 memory. This guide explains how the layer math works, how llama.cpp and vLLM each expose offloading controls, and how to choose a split ratio that keeps the PCI Express bus from becoming the bottleneck during token generation. The analysis below draws on manufacturer hardware specifications, published benchmark architectures, and verified owner feedback from community deployments. It does not represent independent bench measurements conducted by the author.
Understanding the Memory Hierarchy in a Dual-GPU Inference Stack
Every transformer layer in a quantized model consumes a fixed amount of memory for its weights, plus a per-token key-value cache that grows with context length. Before deciding where layers should live, you need three numbers: total weight footprint, KV cache requirement at your target context window, and the usable VRAM on each card after the CUDA context and framework overhead are subtracted. A detailed walkthrough of these calculations is available in our VRAM and KV cache allocation guide, which covers the arithmetic for grouped-query attention models in depth.
The memory hierarchy in this configuration has three tiers with sharply different characteristics. On-card GDDR memory offers the highest bandwidth, typically in the high hundreds of gigabytes per second to over one terabyte per second on current flagship cards, and it is the only tier where matrix multiplications run at full speed. System DDR5 offers large capacity at a fraction of that bandwidth, often between 60 and 90 GB/s on a typical dual-channel desktop and several times that on multi-channel workstation platforms. The PCI Express link sits between them and is frequently the narrowest path of all, especially when a layer’s weights must cross it on every forward pass.
When a layer is offloaded to CPU memory, the runtime must either execute that layer on the CPU using DDR5 bandwidth or stream its weights to the GPU for each token. Both paths are substantially slower than resident VRAM execution. This is the central tradeoff: offloading buys capacity at the cost of latency, and the penalty scales with the number of offloaded layers and the number of tokens generated.
Pipeline Parallelism Versus Tensor Parallelism
Two distinct strategies exist for splitting a model across multiple GPUs, and they behave very differently under PCIe constraints. Pipeline parallelism assigns contiguous blocks of layers to each device. GPU 0 holds layers 0 through N, GPU 1 holds layers N+1 through the final layer, and only the activation tensor for a single token crosses the interconnect at the boundary. Communication volume per token is small and fixed, which makes pipeline parallelism tolerant of modest PCIe bandwidth.
Tensor parallelism splits individual matrix multiplications across devices. Each GPU computes a slice of every layer, and the partial results must be combined through an all-reduce operation after each layer. This produces far more inter-GPU traffic per token. Tensor parallelism delivers better throughput when the cards share a high-bandwidth link such as NVLink, but over PCIe alone the synchronization overhead can erase the benefit and, at small batch sizes, make a single GPU faster. vLLM supports tensor parallelism through its tensor-parallel-size setting and is best suited to configurations where interconnect bandwidth is adequate. llama.cpp defaults to a layer-split approach that behaves more like pipeline parallelism, which is usually the safer choice on PCIe-only systems.
Configuring Layer Offloading in llama.cpp
llama.cpp exposes its offloading behavior through a small set of command-line parameters. The -ngl flag, or –n-gpu-layers, specifies how many transformer layers reside on the GPU. Any layers beyond that count remain in system memory and are executed on the CPU. For a dual-GPU setup, the –split-mode flag selects how layers are distributed, and –tensor-split accepts a ratio that determines what fraction of the offloaded model each card receives.
A representative invocation for a 70B quantized model with 80 transformer layers on two cards of unequal capacity might look like the following conceptual configuration: set the GPU layer count to the maximum that fits across both cards after reserving headroom for the KV cache, set the split mode to layer, and weight the tensor-split ratio to match the free VRAM on each device rather than their nominal capacity. Free VRAM is the operative number because the display driver, desktop compositor, and any background processes consume a non-trivial share, particularly on the card driving monitors.
Layer count should be tuned empirically by starting high and reducing until the model loads without out-of-memory errors at your intended context length. Reserve a margin of roughly ten to fifteen percent for compute buffers, which llama.cpp allocates separately from weights and which scale with batch size and context. Loading succeeds at startup but failure often appears only when a long prompt is processed, so test with a context near your practical maximum before committing to a configuration.
Configuring Tensor Parallelism in vLLM
vLLM takes a different approach and prioritizes throughput under concurrent request loads through paged attention and continuous batching. Multi-GPU operation is controlled primarily by the tensor-parallel-size parameter, which must divide evenly into the model’s attention head count. Setting this to two shards every layer across both cards. The gpu-memory-utilization parameter sets the fraction of each card’s memory the engine may claim, with the remainder reserved for activations and overhead. A value between 0.85 and 0.92 is typical for dedicated inference hosts, but a card that also drives a display should be set lower.
vLLM does not offer native fractional CPU offloading of arbitrary layers in the way llama.cpp does, and its CPU offload option is designed around specific weight-streaming scenarios that carry significant latency penalties. For operators whose primary constraint is DDR5 capacity rather than VRAM, llama.cpp is generally the more direct tool. For operators with two cards connected by a fast link who need batched throughput, vLLM with tensor parallelism is the stronger choice. The interconnect determines which approach is viable, and this is the decision point where hardware topology matters most.
Diagnosing and Avoiding PCI Express Bus Saturation
The PCI Express specification defines per-lane throughput that doubles with each generation, and a x16 link on a current platform provides substantially more bandwidth than a x8 or x4 link. The governing reference for these figures is the PCI-SIG High-Speed Interconnect Standards, which document the signaling rates and encoding overhead that determine effective throughput. Effective bandwidth is always lower than the raw signaling rate because of protocol overhead, and it is shared when multiple devices contend for the same root complex.
Bus saturation during token generation typically manifests in one of several ways. GPU utilization drops in a sawtooth pattern while the CPU or PCIe controller is busy moving weights. Tokens-per-second falls disproportionately as offloaded layer count rises, and the decline is steeper than a simple bandwidth ratio would predict. These symptoms indicate that offloaded layers are being streamed across the bus repeatedly rather than computed in place.
Mitigation strategies include keeping the offloaded layer count as low as capacity allows, placing both GPUs on x16 or at least x8 electrical links where the motherboard supports it, and avoiding configurations where one card shares lanes with storage controllers or network adapters that generate concurrent traffic. Checking the negotiated link width and generation with system monitoring tools confirms whether a card has trained at its expected speed, since a slot can silently fall back to a narrower link. Platform lane allocation is a common hidden constraint on consumer boards, and workstation platforms with more PCIe lanes provide meaningfully more headroom for dual-GPU inference.
Choosing the Right Hardware Baseline for Dual-GPU Inference
Hardware selection determines how much of the tuning above is necessary. Cards with larger per-device VRAM reduce the number of layers that must be offloaded at all, which keeps the workload entirely on high-bandwidth memory. Comparing the generational differences in memory capacity, bandwidth, and interconnect support is a useful starting point, and our RTX 5090 vs RTX 4090 local AI comparison examines how these factors translate to inference workloads. For builders planning a complete system around multiple accelerators, the dual RTX 5090 workstation architecture review addresses chassis airflow, power delivery, and lane topology in a multi-GPU context.
| Specification | Single Card Offload | Dual Card Layer Split (llama.cpp) | Dual Card Tensor Parallel (vLLM) |
|---|---|---|---|
| Architectural model | Resident VRAM plus CPU spill | Pipeline-style contiguous layer blocks | Sharded matrix operations per layer |
| Memory bandwidth dependency | GDDR and DDR5 for spill layers | GDDR per card, DDR5 for remainder | GDDR per card, high-bandwidth link preferred |
| PCIe traffic per token | Activation transfer to CPU layers | Single activation tensor at boundary | All-reduce after each layer |
| Compute metric sensitivity | Limited by CPU throughput on spill | Balanced across two GPUs | Scales with interconnect quality |
| Best practical use case | Single-user, capacity-constrained | PCIe-only systems, single-user latency | Batched serving with fast interconnect |
Power and Thermal Planning for Sustained Inference
Two high-end accelerators running sustained inference draw substantial power, and the peak transient load of the platform can exceed what a standard household circuit or small UPS can deliver. Power supply sizing should account for both GPUs at their rated board power plus CPU, memory, and storage, with headroom for transient spikes. Operators running inference in environments without reliable grid power should size backup systems accordingly, and our guide to high-wattage backup power loads walks through the arithmetic for continuous and surge demand.
Thermal design matters as much as electrical capacity. Dual cards in adjacent slots often recirculate exhaust heat, reducing boost clocks and increasing memory junction temperatures over long generation runs. Sustained throughput is a better planning metric than peak burst performance, and a case with adequate front-to-back airflow and sufficient spacing between cards generally preserves performance across hour-long sessions. Memory temperatures deserve particular attention because throttling on GDDR affects bandwidth, and bandwidth is precisely what determines offload penalties.
Workstation Display and Environment Considerations
Inference workstations often run continuously and display long-lived monitoring dashboards, log windows, and model interfaces. Static elements on high-brightness panels can cause uneven wear over time, which makes display configuration a practical part of long-term operation. Guidance on reducing this risk appears in our workstation display maintenance article, including pixel refresh scheduling, brightness management, and screen timeout settings that suit always-on inference hosts.
Practical Tuning Workflow Summary
A reliable procedure begins with measuring the actual free VRAM on each card with no model loaded, then calculating the weight footprint of the target quantization and the KV cache required at your maximum context length. Load the model with the highest GPU layer count that fits with a safety margin, and benchmark generation throughput at short and long contexts. If tokens-per-second collapses when offloaded layer count increases, reduce the offload ratio or adjust the tensor split so that the slower card carries fewer layers. Verify PCIe link width and generation, and confirm that no competing device is contending for the same root complex.
Offloading LLM layers across dual GPUs and system DDR5 is ultimately an exercise in managing a bandwidth hierarchy. Keeping as much computation as possible on resident high-bandwidth memory, choosing a parallelism strategy matched to your interconnect, and treating the PCIe link as a scarce resource produces the most predictable results. The configurations described here are a starting framework, and the correct values for any given system emerge from measuring its specific memory capacity, link topology, and workload profile.









